When my daughters were younger, I’d sit at the kitchen table while they did their homework. One would be sounding out words, the other trying to remember how fractions worked—both frustrated in their own ways. I’d remind them, “You don’t have to know everything. You just have to keep getting better. Make stubbornness your superpower.”
Some nights they’d ask, “Dad, how come you are so smart?”
I never had a clean answer. Grades? I got horrible grades. Tests? I did poorly on tests. Curiosity? Yes. I was curious, and I made up my mind to keep asking—and answering—the right questions.
That memory makes an uneven profile of ability feel familiar. It also gives us a reason to be careful when we borrow the language of human intelligence to describe a machine. A chart can help us ask better questions without explaining everything about the thing being measured.
A Proposed Ruler
The AGI Definition Project proposes a framework grounded in Cattell–Horn–Carroll theory, a model of human cognitive abilities. It organizes evaluation across ten domains, including knowledge, reasoning, perception, and memory, with a well-educated adult as its reference for general capability.
This is a proposal for making a difficult idea more explicit. It is not the first attempt to evaluate AI, and it is not a settled definition of intelligence. Choosing domains, tests, and reference levels is part of constructing the ruler.
There is value in making those choices visible. “It seems smart” gives us little to inspect. A profile lets us ask where a system performs well, where it struggles, and whether the tests capture what we care about.
What the Numbers Mean
The project reports aggregate scores of 27% for GPT-4 and 58% for GPT-5. Read those as results within the proposed framework. They are not percentages of a human mind, percentages of all jobs a model can perform, or a linear measure of distance to AGI.
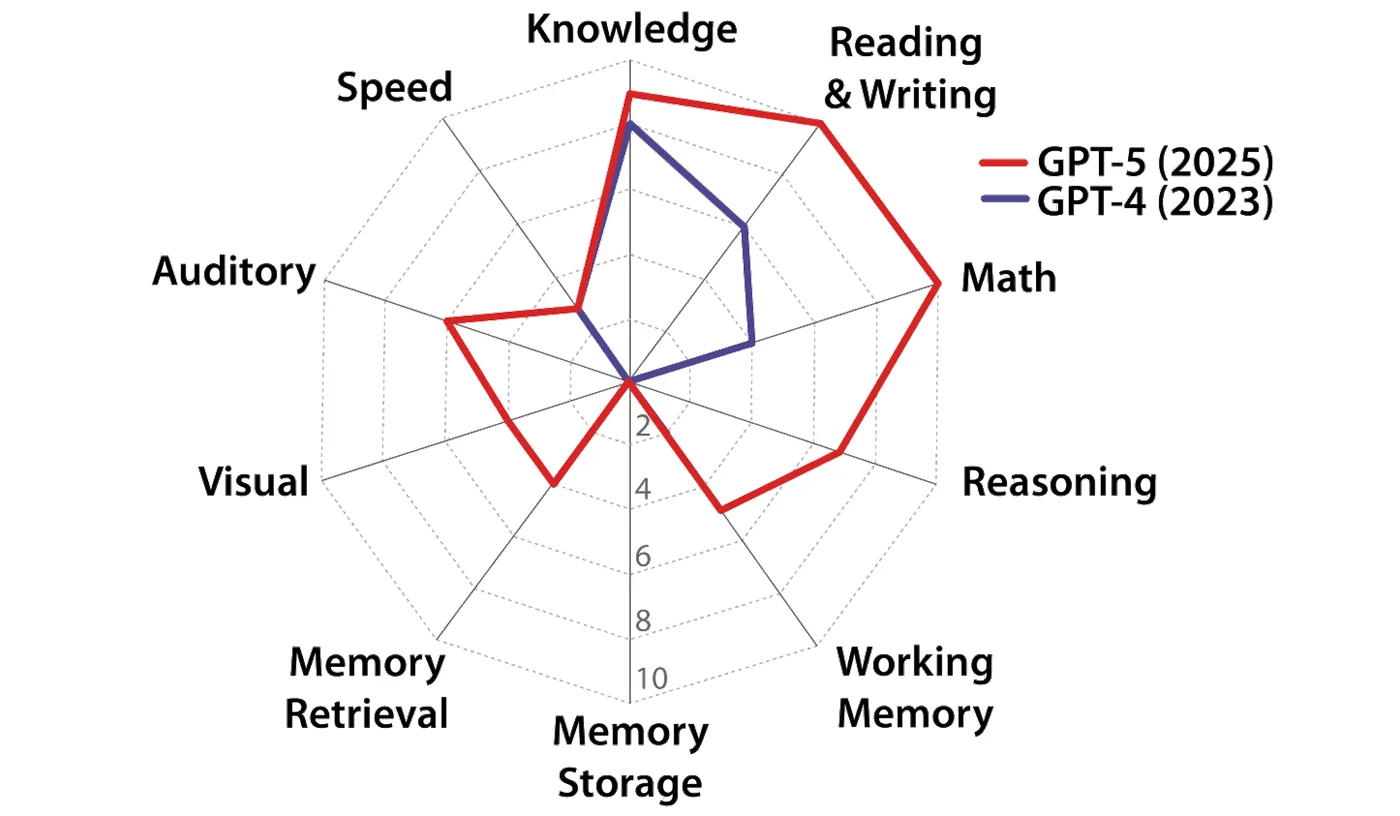
The comparison is between model generations, not a controlled measurement of one year’s learning. It cannot tell us that another equal-sized jump will occur in the next year. Nor does reaching a reference score on a set of mathematics tasks establish that a model works like a trained mathematician in every setting.
The caution was present when the project appeared. In his October 16 discussion, coauthor Gary Marcus calls attention to benchmark limitations and choices about weighting. A useful framework should remain open to better tests rather than become a permanent checklist.
The Shape Is the Useful Question
An aggregate can hide a weakness that matters. A system might produce a strong explanation while failing to retain information needed for a later step. Averaging those results does not repair the missing capability.
That observation changes how we should design a task. Suppose we want an assistant to prepare a project briefing from approved records. We need to know whether it finds the relevant source, distinguishes a decision from a proposal, and carries the right date into the summary. A broad cognitive score does not answer those specific questions.
We can test them. Give the system two records that disagree and see whether it identifies the conflict. Omit a required approval and see whether it asks for it. Ask for the source of a conclusion and inspect the passage it cites. These are proposed checks, not results claimed for either model.
Adding a document store or conversation history may help an application with a memory-related task. That should be evaluated as a system design, separately from a claim about the underlying model’s abilities. The distinction lets us see what actually improved.
Back at the Kitchen Table
The comparison with my daughters has a limit. A child’s growing understanding is part of a life, with experiences, relationships, and reasons to keep trying. A benchmark result cannot establish that an AI shares those qualities.
What the scene still offers is a habit: pay attention to the particular difficulty. A struggle with fractions is a reason to work on fractions. An overall grade may give us a signal, but the next useful step comes from finding the gap.
That is how this chart can help. Use it to ask which ability the work requires, then build a test that exposes failure in that ability. Keep asking the right questions. The point of a ruler is to make our judgment more precise, and that includes knowing what it cannot measure.